# Get Cookies
Source: https://docs.reworkd.ai/api-reference/public/get-cookies
https://api.reworkd.dev/api/openapi.json get /v1/cookies
# Get Latest Reviews
Source: https://docs.reworkd.ai/api-reference/public/get-latest-reviews
https://api.reworkd.dev/api/openapi.json get /v1/reviews/{group_id}
Get the latest review status and comment for a group.
# Get Local Storage
Source: https://docs.reworkd.ai/api-reference/public/get-local-storage
https://api.reworkd.dev/api/openapi.json get /v1/local-storage
# Get outputs for a scraping group
Source: https://docs.reworkd.ai/api-reference/public/get-outputs-for-a-scraping-group
https://api.reworkd.dev/api/openapi.json get /v1/outputs/{group_id}
Allows you to fetch all outputs for a given scraping group. The results are a
materialized view of the outputs for the group; meaning the results are
deduplicated. This view is updated depending on how often the group is scheduled
to be re-scraped.
The results are paginated and sorted by the `create_date` of items in ascending order.
You can fetch the next page by using the `next_url` or `next_cursor` fields in the
response metadata.
Typically, you'd also want to provide a `created_after` filter to only fetch outputs
created after a certain date. This is useful when you want to fetch new outputs
since the last time you fetched outputs; thus allowing you to maintain a "real-time"
view of the outputs.
# Set Cookies
Source: https://docs.reworkd.ai/api-reference/public/set-cookies
https://api.reworkd.dev/api/openapi.json post /v1/cookies
# Set Local Storage
Source: https://docs.reworkd.ai/api-reference/public/set-local-storage
https://api.reworkd.dev/api/openapi.json post /v1/local-storage
# API Keys
Source: https://docs.reworkd.ai/developers/api-keys
Before you can use the Reworkd API, you will need to create an API key for your organization. To do this:
1. Travel to the organization API key page. You may either visit [https://auth.reworkd.ai/org/api\_keys/](https://auth.reworkd.ai/org/api_keys/) directly or click the settings button on the organization menu dropdown
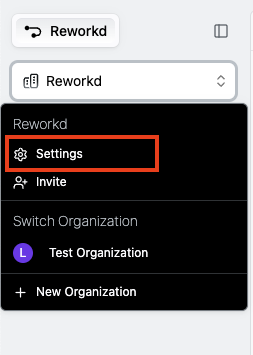 2. Ensure you are on the `Organization API Keys` page
3. Click the `New API key` button and create a new API key with a reasonable expiration date
You should now be able to use your new API key to authenticate your requests. To do this, you will need to add the following header to your requests:
```
Authorization: Bearer
```
# Handling File Downloads
Source: https://docs.reworkd.ai/developers/file-downloads
Different types of file downloads require different code strategies. This page outlines various strategies you may take.
## Regular Download Links
Regular downloads occur when the file link is directly available within the HTML (typically in the `href` of an `` tag). Clicking these links directly initiates a file download.
To handle these downloads:
1. Save the URL directly from the page.
2. Reworkd will then asynchronously visit and download the file. We use `curl-cffi` mimicking browser behavior when downloading the file.
```python theme={null}
# Select the link element
link = await sdk.page.query_selector('a.download')
# Get the URL directly
href = await link.get_attribute("href")
# Save the URL, Lambda will handle the download
await sdk.save_data({"download_url": href })
```
## Indirect Download Links
Indirect downloads happen when the direct link isn't immediately visible but becomes available after clicking a button or link.
To handle indirect downloads:
1. Click the button/link to open the URL.
2. Capture and save the newly loaded URL.
3. Automatically navigate back.
```python theme={null}
# Select element to open page
element = await sdk.page.query_selector('button.download')
# Capture the URL after clicking
download_url = await sdk.capture_url(element)
# Save URL for download via Lambda
await sdk.save_data({"download_url": download_url })
```
## JavaScript/Dynamic Downloads
Dynamic downloads occur when a file download is triggered by JavaScript events directly in the browser, without a direct URL.
To handle dynamic downloads:
1. Use `capture_download` method to trigger and capture the download directly in the browser.
2. Retrieve the file metadata (URL and title).
```python theme={null}
# Select element triggering download
element = await sdk.page.query_selector('button.download')
# Capture download event directly
download_metadata = await sdk.capture_download(element)
# Save file metadata directly
await sdk.save_data({
"attachment": {
"download_url": download_metadata["url"],
"title": download_metadata["title"],
},
})
```
## Downloads Requiring Cookies/Session
Some sites require the download to occur within the same browser session that accessed the page, making AWS Lambda unsuitable.
In these cases:
* Follow the same approach as dynamic downloads, handling the download directly in the browser context using `capture_download`.
# Scraping SDK
Source: https://docs.reworkd.ai/developers/sdk
As part of code generation, Reworkd generates code in its own custom SDK called [Harambe](https://github.com/reworkd/harambe).
Harambe is web scraping SDK with a number of useful methods and features for:
* Saving data and validating that the data follows a specific schema
* Enqueuing (and automatically formatting) urls
* De-duplicating saved data, urls, etc
* Effectively handling classic web scraping problems like pagination, pdfs, downloads, etc
These methods, what they do, how they work, and some examples of how to use them will be highlighted below.
***
## `save_data`
Save scraped data and validate its type matches the current schema
**Signature:**
```python theme={null}
def save_data(self, data: dict[str, Any], source_url: str | None = None) -> None
```
**Params:**
* `data`: Rows of data (as dictionaries) to save
* `source_url`: Optional URL to associate with the data, defaults to current page URL. Only use this if the source of the data is different than the current page when the data is saved
**Raises:**
* `SchemaValidationError`: If any of the saved data does not match the provided schema
**Example:**
```python theme={null}
await sdk.save_data({ "title": "example", "description": "another_example" })
await sdk.save_data({ "title": "example", "description": "another_example" }, source_url="https://www.example.com/product/example_id")
```
***
## `enqueue`
Enqueue url(s) to be scraped later.
**Signature:**
```python theme={null}
def enqueue(self, urls: str | Awaitable[str], context: dict[str, Any] | None = None, options: dict[str, Any] | None = None) -> None
```
**Params:**
* `urls`: urls to enqueue
* `context`: additional context to pass to the next run of the next stage/url. Typically just data that is only available on the current page but required in the schema. Only use this when some data is available on this page, but not on the page that is enqueued.
* `options`: job level options to pass to the next stage/url
**Example:**
```python theme={null}
await sdk.enqueue("https://www.test.com")
await sdk.enqueue("/some-path") # This will automatically be converted into an absolute url
```
***
## `paginate`
SDK method to automatically facilitate paginating a list of elements.
Simply define a function that should return any of:
* A direct link to the next page
* An element with hrefs to the next page
* An element to click on to get to the next page
And call `sdk.paginate` at the end of your scrape function. The element will automatically be used to paginate the site and run the scraping code against all pages
Pagination will conclude once all pages are reached no next page element is found.
This method should ALWAYS be used for pagination instead of manual for loops and if statements.
**Signature:**
```python theme={null}
def paginate(self, get_next_page_element: Callable[Ellipsis, Awaitable[str | playwright.async_api._generated.ElementHandle | None]], timeout: int = 2000) -> None
```
**Params:**
* `get_next_page_element`: the url or ElementHandle of the next page
* `timeout`: milliseconds to sleep for before continuing. Only use if there is no other wait option
**Example:**
```python theme={null}
async def pager():
return await page.query_selector("div.pagination > .pager.next")
await sdk.paginate(pager)
```
***
## `capture_url`
Capture the url of a click event. This will click the element and return the url
via network request interception. This is useful for capturing urls that are
generated dynamically (eg: redirects to document downloads).
**Signature:**
```python theme={null}
def capture_url(self, clickable: ElementHandle, resource_type: Literal[document, stylesheet, image, media, font, script, texttrack, xhr, fetch, eventsource, websocket, manifest, other, *] = 'document', timeout: int | None = 10000) -> str | None
```
**Params:**
* `clickable`: the element to click
* `resource_type`: the type of resource to capture
* `timeout`: the time to wait for the new page to open (in ms)
**Return Value:**
url: the url of the captured resource or None if no match was found
**Raises:**
* `ValueError`: if more than one page is created by the click event
***
## `capture_download`
Capture a download event that gets triggered by clicking an element. This method will:
* Handle clicking the element
* Download the resulting file
* Apply download handling logic and build a download URL
* Return a download metadata object
Use this method to manually download dynamic files or files that can only be downloaded in the current browser session.
**Signature:**
```python theme={null}
def capture_download(self, clickable: ElementHandle, override_filename: str | None = None, override_url: str | None = None, timeout: float | None = None) -> DownloadMeta
```
**Return Value:**
DownloadMeta: A typed dict containing the download metadata such as the `url` and `filename`
***
## `capture_html`
Capture and download the html content of the document or a specific element.
The returned HTML will be cleaned of any excluded elements and will be wrapped in a proper HTML document structure.
**Signature:**
```python theme={null}
def capture_html(self, selector: str = 'html', exclude_selectors: list[str] | None = None, soup_transform: Callable[BeautifulSoup, None] | None = None, html_converter_type: Literal[markdown, text] = 'markdown') -> HTMLMetadata
```
**Params:**
* `selector`: CSS selector of element to capture. Defaults to "html" for the document element.
* `exclude_selectors`: List of CSS selectors for elements to exclude from capture.
* `soup_transform`: A function to transform the BeautifulSoup html prior to saving. Use this to remove aspects of the returned content
* `html_converter_type`: Type of HTML converter to use for the inner text. Defaults to "markdown".
**Return Value:**
HTMLMetadata containing the `html` of the element, the formatted `text` of the element, along with the `url` and `filename` of the document
**Raises:**
* `ValueError`: If the specified selector doesn't match any element.
**Example:**
```python theme={null}
meta = await sdk.capture_html(selector="div.content")
await sdk.save_data({"name": meta["filename"], "text": meta["text"], "download_url": meta["url"]})
```
***
## `capture_pdf`
Capture the current page as a pdf and then apply some download handling logic
from the observer to transform to a usable URL
**Signature:**
```python theme={null}
def capture_pdf(self) -> DownloadMeta
```
**Return Value:**
DownloadMeta: A typed dict containing the download metadata such as the `url` and `filename`
**Example:**
```python theme={null}
meta = await sdk.capture_pdf()
await sdk.save_data({"file_name": meta["filename"], "download_url": meta["url"]})
```
***
## `log`
Log a message via both `print` and `console.log` if a browser is running
Concatenates all arguments with spaces.
Args:
\*args: Values to log (will be concatenated)
**Signature:**
```python theme={null}
def log(self, args) -> None
```
# Deduplication
Source: https://docs.reworkd.ai/features/deduplication
Automatically generate scrapers
Reworkd automatically handles deduplicating data whenever your scrapers re-run.
## How It Works
When saving data, Reworkd uses a **unique key** (or composite key) based on the record's fields to determine if the data is new or if it is a duplicate of data that has already been saved.
| Scenario | Action Taken by Reworkd |
| ---------------------------------------------------------- | --------------------------------------------------------------------------- |
| **New row of data saved** | Inserts data and marks as a `CREATE` change. |
| **Duplicate row of data saved** | Skips insertion; no duplicate is created. |
| **Updating data that has been seen before (existing key)** | Updates existing record without duplication and marks as an `UPDATE` change |
## Defining your Deduplication Key
When you are creating your schema, you must also select which of the fields you want to use as part of your **primary/deduplication key**.
This deduplication key is critical to ensure you avoid duplicated data. It must:
* ✅ **Be unique** for every output row.
* ✅ **Remain stable** over time (avoid frequently changing fields).
* ✅ **Be consistent**. Regardless of what website you are on, this key must be the same for the same item.
If there is no one obvious key field, use multiple attributes to create a reliable **composite key**.
## Good vs. Poor Key Examples
#### Good key choices
* Unique ID like a **SKU** or **UPC**
* Combination of unique attributes like **Brand + Model + Color**
#### Poor key choices
* Price (frequently changes)
* Availability status (frequently fluctuating)
* Timestamp of last update
# API Exports
Source: https://docs.reworkd.ai/features/exports/api-exports
Export data via our APIs
The most common way for our customers to ingest our data is via our API endpoints.
If you haven't already, create an API key by following our [API key documentation](/developers/api-keys) and get started with our API below.
Full API documentation for how to export data from your groups
## Getting only new data
Use the `created_after` query parameter to filter for data created after your last ingestion.
Typically our customers will call our API once a day, keeping track of the exact datetime in which they made the API call.
Any subsequent API calls they make will set `created_after` to the previously recorded datetime.
# Bulk Exports
Source: https://docs.reworkd.ai/features/exports/bulk-exports
Export data via our UI
Bulk exports are JSON or CSV files of all of the scraped data within a group or job.
You create bulk exports in our UI by selecting the group you want to export, and optionally selecting a job and/or a date you want to filter the data by.
Bulk exports are useful for getting a full snapshot of your data at a given point in time but our API exports should be the preferred export method for most use cases.
Note: Running an export for a large group may take a very long time to complete.
Bulk export data from your scraping groups
# Exports Overview
Source: https://docs.reworkd.ai/features/exports/overview
Exporting your data out of Reworkd
Dynamically export data from your groups via our APIs
Create single file exports of entire groups via our UI
# File Downloads
Source: https://docs.reworkd.ai/features/file-downloads
Reworkd can automatically handle downloading files on your behalf. Files are stored in our infrastructure, and download links to these files are provided in all export formats.
## Setting up downloads
To configure automatic downloads:
1. Create a field in your schema with the **URL** type.
2. In the field settings, ensure **Download file from URL** is set to `True`.
3. Create a job that will save the download URL to a file in this field.
Once the job is run, the file linked in that URL will be automatically downloaded.
Note: File downloads happen asynchronously. It may take time for files to appear in your exports.
## Retrieving files
File download links will be included in the `files` array of your exports.
Example API response for file data:
```json theme={null}
{
...
"files": [
{
"id": "70057eca-d05c-4a33-ae84-4af8dce83ce3",
"field": "attachments[0].url",
"url_etag_hash": "92359181252f9b52a4da21599fbf8f8d.pdf",
"s3_key": "test_key.pdf",
"s3_url": "https://files.reworkd.dev/test_url",
"source_url": "https://source-website.com/download/49a42973",
"create_date": "2024-08-26T18:49:31.575000",
"file_url": "s3://deworkd-prod-files/11ee111ee.pdf",
"file_type": "pdf",
"file_checksum": "7eec76e4bd1fed22f5d7d5fa7efbeaf717a77da771bb5c61e09b0d7ae46bbd",
"file_metadata": {
"url": "https://source-website.com/download/49a42973",
"filename": "Test document.pdf",
"dynamic_download": "true"
}
}
],
...
}
```
### Key fields
* `s3_url`: Pre-signed URL to retrieve the file from our S3 bucket.
* `source_url`: Original URL of the file; points to our S3 bucket if no canonical source URL exists. If so, file\_metadata.dynamic\_download will be set to true.
* `field`: Indicates which field in the output data the file relates to.
## How are files downloaded?
#### Regular downloads
Regular downloads occur when files are directly accessible via a URL (e.g., direct PDF links).
* The canonical URL of the file is used and saved
* Files are downloaded asynchronously via AWS Lambda using a dedicated download queue. Delays may occur.
#### Dynamic downloads
Dynamic downloads occur when there is no canonical URL available, typically triggered via JavaScript or requiring active session information.
* Files are downloaded directly in the browser worker to guarantee accuracy.
* Because no canonical link is available, the link to the current page is used as the source URL.
* For more technical details, see Handling file downloading.
## File storage
**We can only guarantee that your downloaded files remain stored within our S3 buckets for 90 days.**
If your use case requires longer retention periods, please let us know!
# Scheduling
Source: https://docs.reworkd.ai/features/scheduling
Re-use scrapers across identical sites
You can schedule groups to be re-run at a specific cadence. To set a schedule, go to the settings tab within a group and select the schedule you want to use.
## Overriding schedules
Often there may be specific sources within a group that you want to run more or less frequently than the rest of the group.
To do this, you can override the schedule for the specific source by going into the settings tab of the job.
## How are pages re-visited?
#### Category/Listing pages
All higher level stages such as category and listing pages will always be re-run in subsequent runs.
They will enqueue and run all of their lower level stages (except for detail pages).
#### Detail pages
Detail page visits are de-duplicated. By we do not revisit detail pages after initially scraping its data by default.
This is because there is no consistent way to detect detail page changes without actually opening the page and re-running the extraction code. If you require detail page re-visits, please reach out to us!
# Templates
Source: https://docs.reworkd.ai/features/templates
Re-use scrapers across identical sites
Note: Templates are not available for hobby plan customers
When scraping, you'll often encounter multiple websites using identical underlying structures or sharing the same web provider.
Instead of repeatedly writing new scrapers for each of these websites—which consumes both your time and LLM tokens—use Templates.
Templates allow you to save and re-use pre-built scraper code.
Once created, templates can be applied to multiple websites with matching structures, without any extra effort required.
This means whenever the structure of these websites changes, you only need to update the template once to instantly fix the issue for all associated sites, rather than manually updating each individual scraper.
# Introduction
Source: https://docs.reworkd.ai/introduction
Reworkd - Extract web data at scale
 Reworkd uses LLMs to parse, understand, and interact with web pages to help users scrape web data at ***scale***.
Reworkd customers are extracting millions of rows of data to help build data constrained products, fine tune domain specific language models, and enrich existing data pipelines.
We also built AgentGPT! If you're looking for info on AgentGPT, please visit our
[Github](https://github.com/reworkd/AgentGPT)
Learn how to scrape a website and its sub pages with Reworkd
Understand all of the key terms required to get started
Learn how to export the data you scrape
Read the latest updates on the Reworkd blog
# Key Concepts
Source: https://docs.reworkd.ai/key-concepts
Everything you need to get started with Reworkd
# Groups
A group is the first thing you create when you use Reworkd.
Groups are a collection of source urls/jobs that share a common schema and scraping frequency.
For example, if you were looking to scrape multiple online bookstores for book data, you might create a **Bookstore** group
and add all of the bookstore source URLs within it.
### Schemas
A schema is a structured definition of the data you want to scrape from a website. Read more about schemas in our [Schemas](/features/schemas) page.
All jobs within a group will share the same schema.
# Jobs
A job represents a distinct source URL within a scraping group.
We break jobs down to various stages as a scraper flows through a website and enqueues additional pages.
We consider the first job the source job, and any jobs that get enqueued by the source job are considered child jobs.
Jobs can be configured with various settings such as proxy types, timeouts, and other parameters to optimize the scraping process for different page requirements.
### Stages
Every job is associated with a specific type of stage. Suppose you are wanting to scrape an e-commerce website.
1. The first stage might be the **category** page. This page would list all of the different categories of products available on the site such as shirts, pants, shoes, etc.
This job would go through and enqueue all of these categories as listing pages.
2. Each **listing** page would just be all of the products under a specific category. For example, it may be a list of pants.
Listing jobs would just go through each page of the list and enqueue the associated product detail page.
3. Finally, the **detail** page would be the final page. This page contains all of the information about a specific product. This job would just save the data of the product and be done.
# Run
A `Run` is a single execution of a scraping job.
Job runs are essential for tracking the status and results of each scraping attempt, ensuring data is consistently collected and processed correctly;
they can also be retried upon failures to enhance data accuracy.
Additionally, job runs often generate a list of outputs, capturing the extracted data or links to be further processed.
# Schemas
Source: https://docs.reworkd.ai/schemas
Schemas are the definition for the exact data format you expect websites within a particular group to use.
Every row of data Reworkd processes will go through a strict schema validation process to guaranteed your data is consistent with your schema.
## Schema field types
Schemas support both basic data types like strings and numbers along with a collection of advanced fields that apply transformations to the data:
* **URL**: A string field that transform relative URLs into absolute URLs and fail if an invalid URL is provided. URL fields will also allow you to download files from whatever URL is provided. See the Downloading files page for more information.
* **Phone Number**: A string field that will case cast values to known phone number types
* **Currency**
## What makes for a good schema?
How well you can scrape a page is is heavily impacted by your schema choices. Here are some loose guides on making a good schema:
1. Simple. The less fields there are, the less room for error there.
2. Only use fields you need today. Do not build schemas for fields you probably won't need
3. Ensure schema fields actually appear on the page.
* Do not include nice-to-have fields that never actually appear on any website
* Do not include fields that are only present in one of your 10s/100s/1000s of websites
4. **Capture fields as they appear on the page.** If they appear as arbitrary strings but your system requires them to be in domain specific enums, capture them as strings and create your own post processing layer to transform them as necessary
5. Avoid derived field: fields that are generated from other fields in the schema. Derived fields should be handled in your own application code
6. Ensure fields are unambiguous
* Carefully name fields as they appear on websites
* Provide field descriptions and example values where possible to clarify ambiguity. Clarify industry specific naming jargon and describe all of the different aliases that a given field may go by on the site
7. Use advanced fields if possible. They abstract away some of the complexities of data transformations from LLMs leading to lower failures and higher data consistency
## What if the page is missing fields?
Often not every website will conform to the unified schema you’ve created.
Sometimes individual pages may be missing fields while other times the entire website itself may not present a field.
If the field is missing, it will be left as null in the output. If it is an array, it will be left as an empty array.